Trending Topics

 Trending
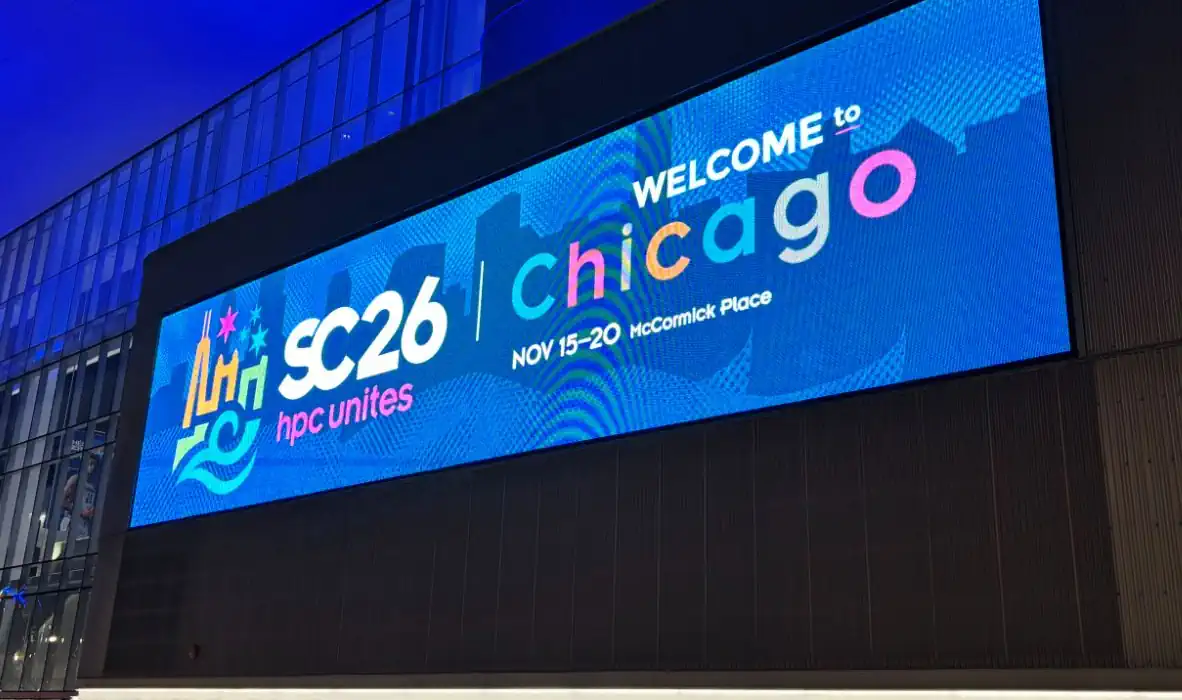
Intel spells out its vision for the next generation of supercomputing as SC26 begins

Poor old Nvidia. Everywhere you turn people are having a poke at the company, including in Intel’s statement on the “next chapter” of supercomputing. Written by Jeff McVeigh, VP and General Manager of Intel’s Data Center Strategic Programs, it states that “we believe the future of HPC systems is open, heterogeneous and balanced”, where HPC stands for high-performance computing. And Nvidia stands pretty much alone in the industry in defence of its closed, CUDA-based approach.
So, as Supercomputing 2026 (SC26) moves into its second day, what else does Jeff have to say about the future of HPC and supercomputing? Here’s my hot take.
The CPU still rules, okay?
This is something I also heard from AMD when announcing EPYC Venice based on Zen 6 and Zen 6c: that AI workloads, and other HPC workloads, still need a powerful CPU to orchestrate things. There’s an element of “well they would say that”, but both AMD and Intel have a point.
“For the core of any supercomputing system, the CPU remains the foundational engine – from running highly parallel scientific applications to orchestrating heterogeneous workflows,” wrote Jeff. And I believe most people would agree.
Intel reckons Diamond Rapids is the answer
I found it interesting that rather than point to its current generation of Intel Xeon chips, Jeff instead referred to Diamond Rapids as the answer to HPC problems. This is Intel’s next-generation server architecture, due for release next year.
Perhaps this is because AMD has already started shipping its EPYC Venice silicon (to quote one of its speakers from the AMD In Depth conference I attended, “where we see a need for HPC, there’s a very strong pull for our Venice-based solutions”).
AMD’s EPYC Venice rollout is far from complete, with some families due for release in the second half of 2027, but Intel knows that it still has catching up to do in terms of core count and instructions per clock. Both crucial ingredients in HPC.
Here’s what Diamond Rapids promises, according to Jeff:
- More compute: Stronger “per-thread performance” and “scaling up to 256 performance cores to efficiently handle highly parallel scientific workloads”.
- More memory bandwidth: up to “1.6TB/s of bandwidth, along with up to 1.28GB of last-level cache to keep critical datasets closer to the compute engine”.
- Better built-in acceleration: In particular, Intel AVX 10.2, enhanced Intel Advanced Matrix Extensions (Intel AMX), “which make next-gen Xeon the only x86 server CPU with built-in matrix compute for HPC and AI workloads”
AI-enabled research needs memory capacity
Raw FLOPS enough aren’t alone, says Jeff. In particular, he flags the Intel GPU D-series that offer up to 480GB of LPDDR5X, all in a conventional, air-cooled PCIe card.
“For research environments, memory capacity can directly affect how efficiently large datasets and models are processed,” he said. “When data must be repeatedly partitioned or transferred between host and accelerator, additional overhead can slow scientific workflows. Keeping larger working datasets on-device can help reduce that movement and enable the accelerator to spend more time doing useful work.”
This is a fair point and it’s one area where Intel does potentially hold an advantage over both AMD and Nvidia PCIe accelerators. Let’s watch this space.
Software portability beats proprietary lock-in
Going back to the opening theme of this article, Intel (and AMD, and many others) are keen to point out that the international scientific community depends on openness. Anything that locks data away, that makes it difficult to confirm or challenge, is not a good thing.
“Decades of accumulated code and optimization represent some of the most valuable achievements in the HPC community,” began Jeff. “Hardware innovation loses its practical value if it introduces software friction, forcing development teams into proprietary ecosystems that restrict code portability.”
So what we need, he argues, is a single open stack. In particular, that means continued investment oneAPI, Intel MPI, Fortran and upstream AI frameworks.
“Ultimately, performance is not a static specification on a datasheet,” said Jeff, “it is the ongoing result of collaborative, application-level optimization.”
The next frontier is light
We’ve all heard the complaints about sprawling data centres eating up space, electricity and water. While things are never quite that simple in reality – for a start, there are good data centres and bad data centres when it comes to sustainability – if we look to the future we can certainly imagine ever-bigger warehouses full of super-cooled supercomputers. Is there another way to scale?
The answer, Intel believes, is silicon photonics. This technology allows huge quantities of data to be beamed via optical waveguides across vast distances, and all using far less electricity than the current copper-based approach.
“This optical connectivity represents a systemic shift in how accelerators, memory, and compute will be networked in tomorrow’s supercomputers,” wrote Jeff. And that’s impossible to argue with.
About The Author

Tim Danton
NEXT UP